0
0
ProgrammingDEV Community ·
How std::mem::forget Silently Leaks Heap Memory and Triggers Linux OOM Kills
Rust's std::mem::forget function drops a stack-allocated handle without executing destructor logic, permanently orphaning the associated heap metadata inside allocator arenas. Because the operation produces no undefined behavior, tools like memory sanitizers raise no alerts and the Linux kernel logs no faults at the time of the call. Over weeks of sustained production throughput, the leaked allocations cause the process's Resident Set Size to grow monotonically, fragmenting virtual memory without generating panics or heap corruption reports. Eventually, the Linux kernel's Out-Of-Memory killer issues an uncatchable SIGKILL to the process, leaving engineers with no crash dump to diagnose. The root cause lies in how ManuallyDrop suppresses Rust's drop elaboration pass, preventing the compiler from emitting any call to the allocator's deallocation hook.
0
IndiaTimes of India ·
US Dog Waste Removal Startup Grows from $1,000 to $200,000 Monthly Revenue
Swoop Scoop, a dog-waste removal company, was founded in Washington in late 2020 with an initial investment of just $1,000. The business began by serving only 20 clients but has since scaled to hundreds of subscribers across the United States. Operating on a subscription-based model, the company now generates over $200,000 in monthly revenue. Swoop Scoop has expanded its presence into multiple US markets, demonstrating strong demand for specialized pet waste management services.
0
ProgrammingDEV Community ·
Five-Step 'Ship Gate' Checklist Aims to Catch AI Feature Failures Before Launch
A pre-deployment framework called 'Ship Gate' has been proposed to address a recurring pattern where AI features pass internal demos but break in production. The checklist covers five areas: threat modelling, data boundaries, evaluation sets, human override controls, and observability. A real-world case is cited where an AI email summariser invented a discount offer on its first day live, causing customer support issues that a basic gate could have prevented. The framework argues that most AI failures stem not from the underlying model but from skipping structured pre-launch checks in favour of demo-ready builds. Ship Gate is positioned as a minimal, afternoon-length review rather than a lengthy compliance exercise, designed to ensure AI features earn production deployment instead of learning from live customer mistakes.
0
ProgrammingHacker News ·
CrowdSec Confirms Accidental Source Code Exposure in Security Incident
CrowdSec, a cybersecurity company, has publicly acknowledged an unintended exposure of its source code. The company issued an official statement on its blog addressing the incident. The leak involved the exposure of CrowdSec's codebase, raising concerns within the security community. CrowdSec has communicated transparently with users by publishing details of the event on its website.
0
ProgrammingHacker News ·
GitLab.com to update rate limits in 2026
GitLab has announced upcoming changes to rate limits on its GitLab.com platform, set to take effect in 2026. Rate limits control how frequently users and automated systems can make requests to the service. The changes were detailed in an official GitLab blog post, though specific new thresholds were not summarized in the available content. Such updates typically aim to improve platform stability, reduce abuse, and ensure fair resource distribution among users.
0
ProgrammingDEV Community ·
Deterministic Linting Tools Offer Safer Guard Rails for AI-Generated DB Migrations
AI coding agents can draft database migrations quickly but frequently produce unsafe SQL that fails on production tables with existing rows or causes prolonged lock contention. The problem is structural: safe and dangerous migration patterns look nearly identical in code, and models never encounter the production-scale consequences that reveal the difference. Using a second AI model to review migrations is unreliable because results vary between runs and the model cannot enumerate which rules it actually checked. A deterministic rule-based linter called Bolvrk addresses this by running the same fixed corpus of checks — covering patterns like adding a NOT NULL column without a default or creating an index without CONCURRENTLY — inside the agent's loop via MCP, in the terminal via CLI, and on pull requests via GitHub Actions. The approach ensures the migration verdict remains consistent at every stage, preventing agents from bypassing safety checks that depend on fixed, verifiable logic rather than variable model output.
0
ProgrammingDEV Community ·
One SQL line prevents database outages during table migrations, yet few use it
A common PostgreSQL migration pattern — adding a nullable column with no default — can silently take an entire table offline, not because the operation is slow, but because it queues behind any idle transaction holding a lock. Since ALTER TABLE requires an ACCESS EXCLUSIVE lock, it blocks in the queue, and every subsequent read or write then stacks behind it, effectively freezing application traffic. Engineers at DEV Community reproduced this on PostgreSQL 16, where a 26-millisecond point-read waited over 26 seconds due to an idle session holding an unrelated lock. The fix is a single line added before the migration: SET lock_timeout = '2s', which causes the ALTER to abort after two seconds of waiting rather than clogging the lock queue. Unlike statement_timeout, lock_timeout only limits how long a statement waits for a lock, making it safe to use without risking cancellation of legitimate long-running operations like index builds.
0
ProgrammingDEV Community ·
CREATE INDEX CONCURRENTLY: When It Helps, What It Costs, and What Can Go Wrong
PostgreSQL offers two ways to build indexes in production: the standard CREATE INDEX, which blocks all writes for the entire build duration, and CREATE INDEX CONCURRENTLY, which avoids write locks but takes significantly longer to complete. Benchmarks on a 20-million-row table show the plain form blocked inserts for over 4 seconds, while the concurrent form kept the worst wait under 125 milliseconds. The concurrent build scans the table twice and waits for open transactions to close, making it slower but far safer on live, write-heavy tables. However, if a concurrent build fails midway due to a deadlock or cancellation, it leaves behind an invalid index that consumes write overhead without ever being used by the query planner. Developers should routinely query pg_index for invalid indexes after migrations and drop them using DROP INDEX CONCURRENTLY to avoid silent performance degradation.
0
ProgrammingDEV Community ·
How to Add Foreign Keys to Large PostgreSQL Tables Without Blocking Writes
Adding a foreign key to a large PostgreSQL table using a single ALTER TABLE statement locks both tables for the entire duration of validation, which can block writes for minutes on busy systems. PostgreSQL offers a two-step alternative: first add the constraint with NOT VALID to record it instantly with only a brief lock, then run VALIDATE CONSTRAINT separately under a weaker lock that still permits inserts, updates, and deletes. The end result is the same validated constraint, but with far less disruption to live traffic. Additionally, PostgreSQL does not automatically index the referencing column of a foreign key, so creating one with CREATE INDEX CONCURRENTLY is recommended to prevent slow sequential scans during parent-row deletions. The same NOT VALID and validate pattern also applies to CHECK constraints and can be used to safely enforce NOT NULL on large tables without an expensive full-table lock.
0
ProgrammingHacker News ·
Insufficient source content to generate a reliable summary
The provided source contains only a URL and engagement metrics, with no article body or verifiable facts. No meaningful summary can be produced without fabricating information. Please provide the full article text for accurate reporting.
0
SportsESPNcricinfo ·
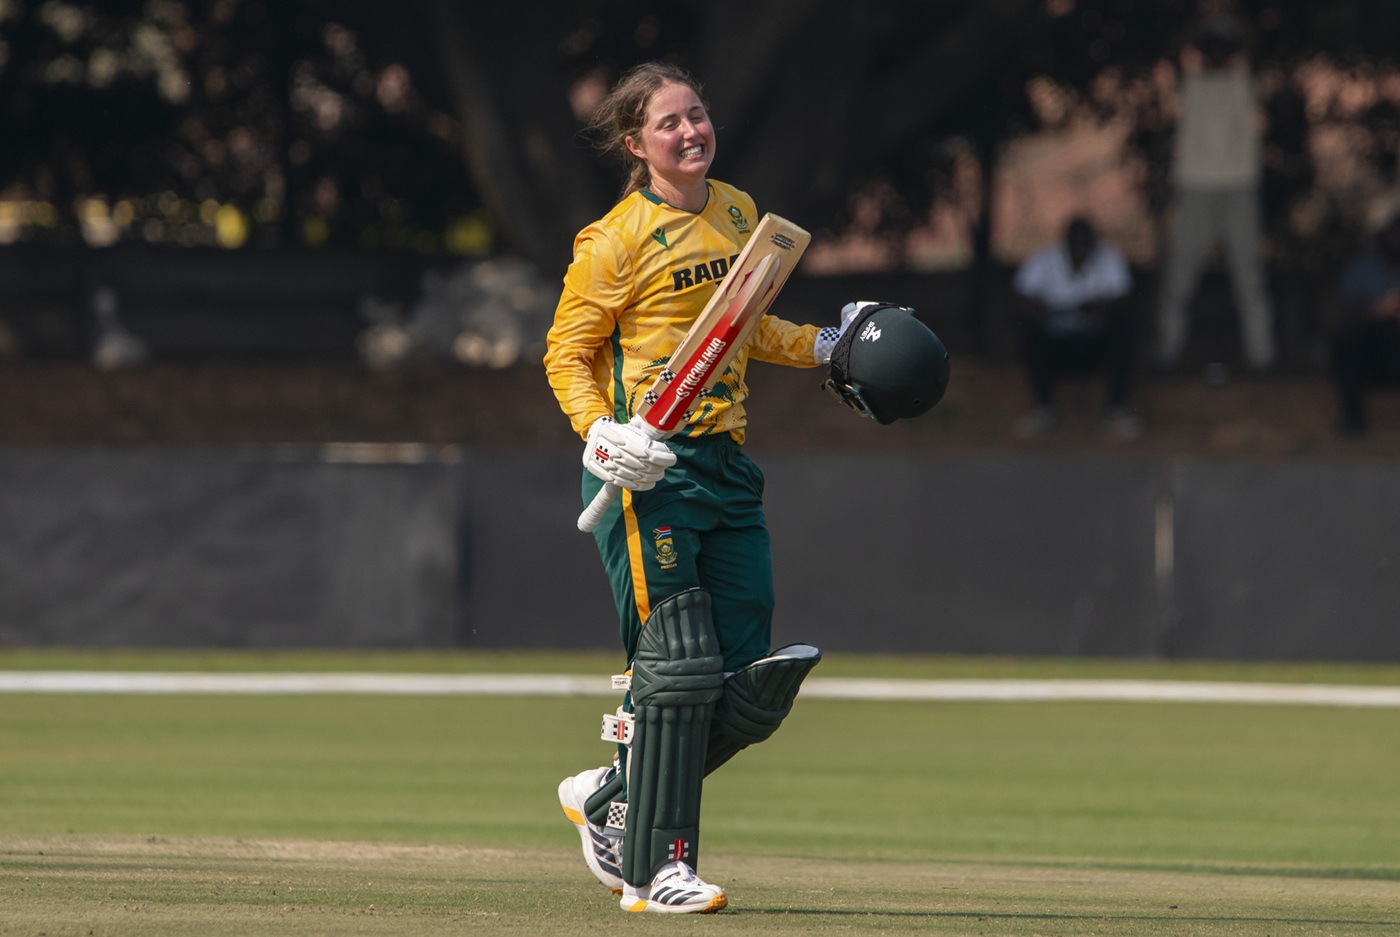
Smit's Maiden T20I Ton Powers South Africa to 4-0 Series Lead Over Zimbabwe
Miane Smit scored her maiden T20I century to propel South Africa to a commanding series victory over Zimbabwe. South Africa posted 205 for 4, their third-highest ever T20I total, setting a formidable target. The total proved far too steep for Zimbabwe, who fell short by 80 runs. The result gave South Africa an unassailable 4-0 lead in the series.
0
0
SpaceNASA ·
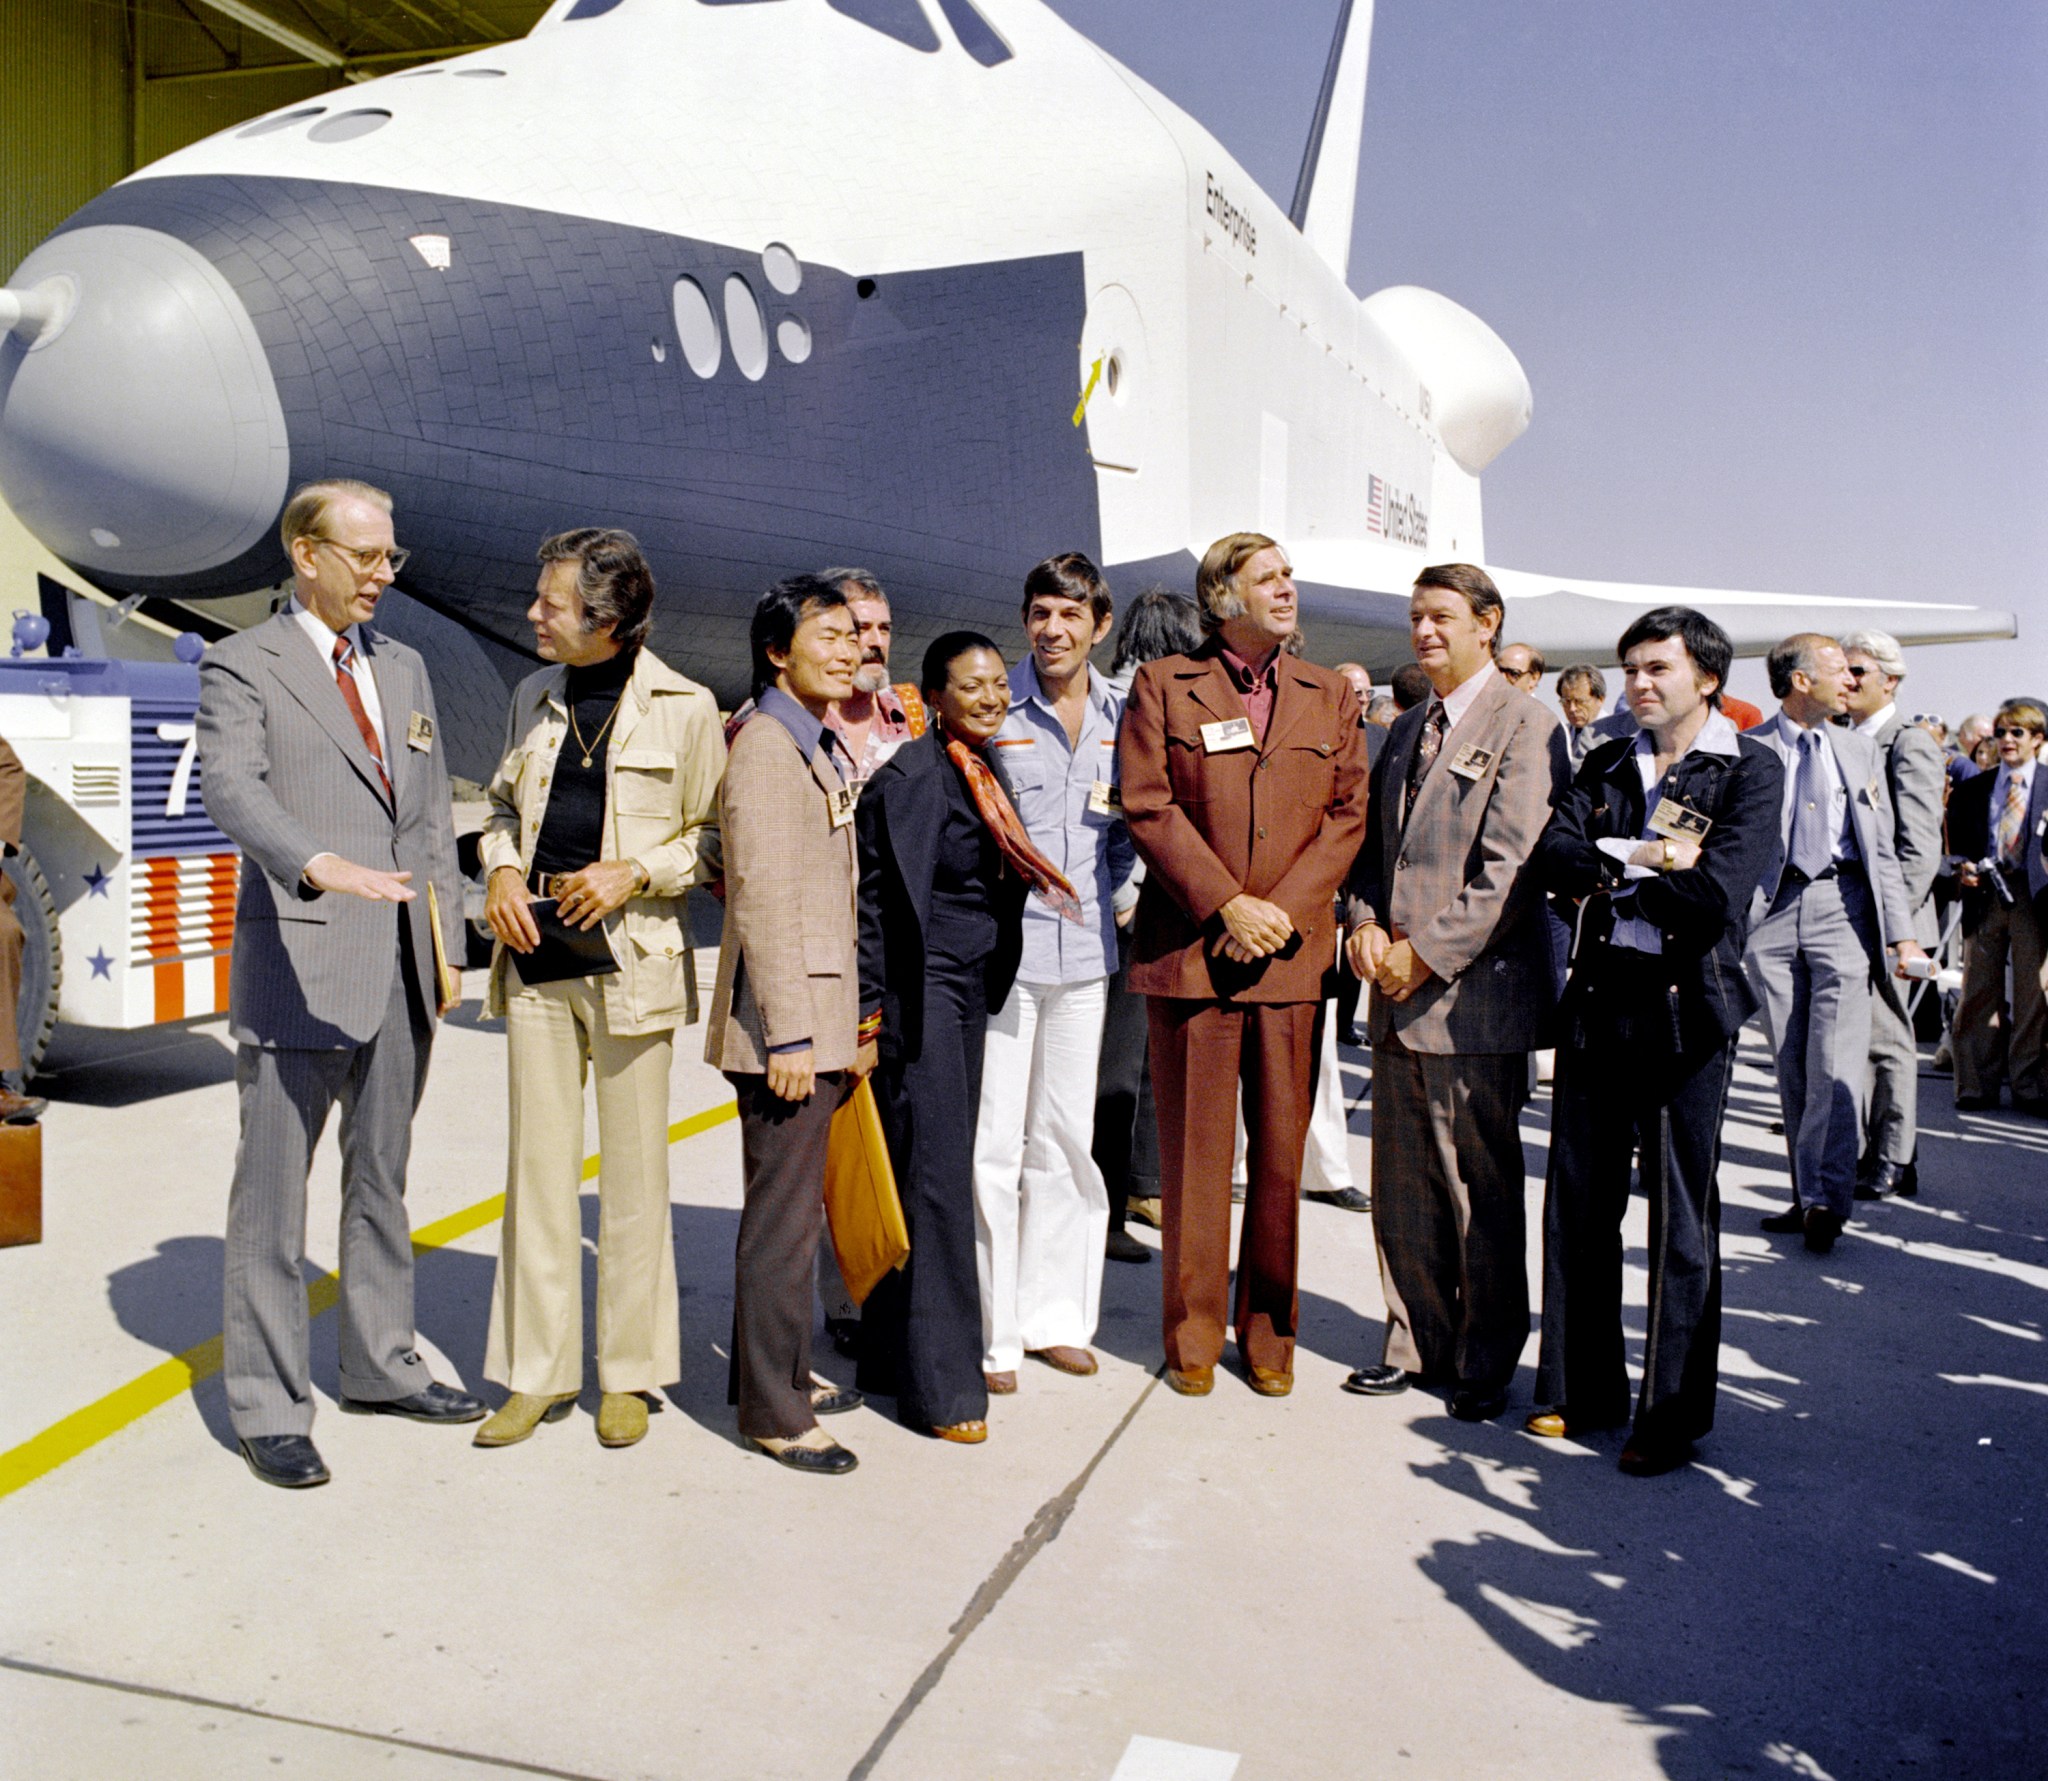
NASA Marks 50 Years Since First Space Shuttle Enterprise Was Unveiled
NASA unveiled its first space shuttle orbiter, designated OV-101, to the public on September 17, 1976, coinciding with Constitution Day during America's bicentennial year. The agency had originally planned to name the vehicle Constitution, but a massive public campaign altered that decision. Nearly 100,000 Star Trek fans wrote to the White House urging NASA to name the shuttle Enterprise, after the iconic spacecraft from the television series. The campaign proved successful, and the orbiter was officially named Enterprise before its public debut.
0
IndiaTimes of India ·
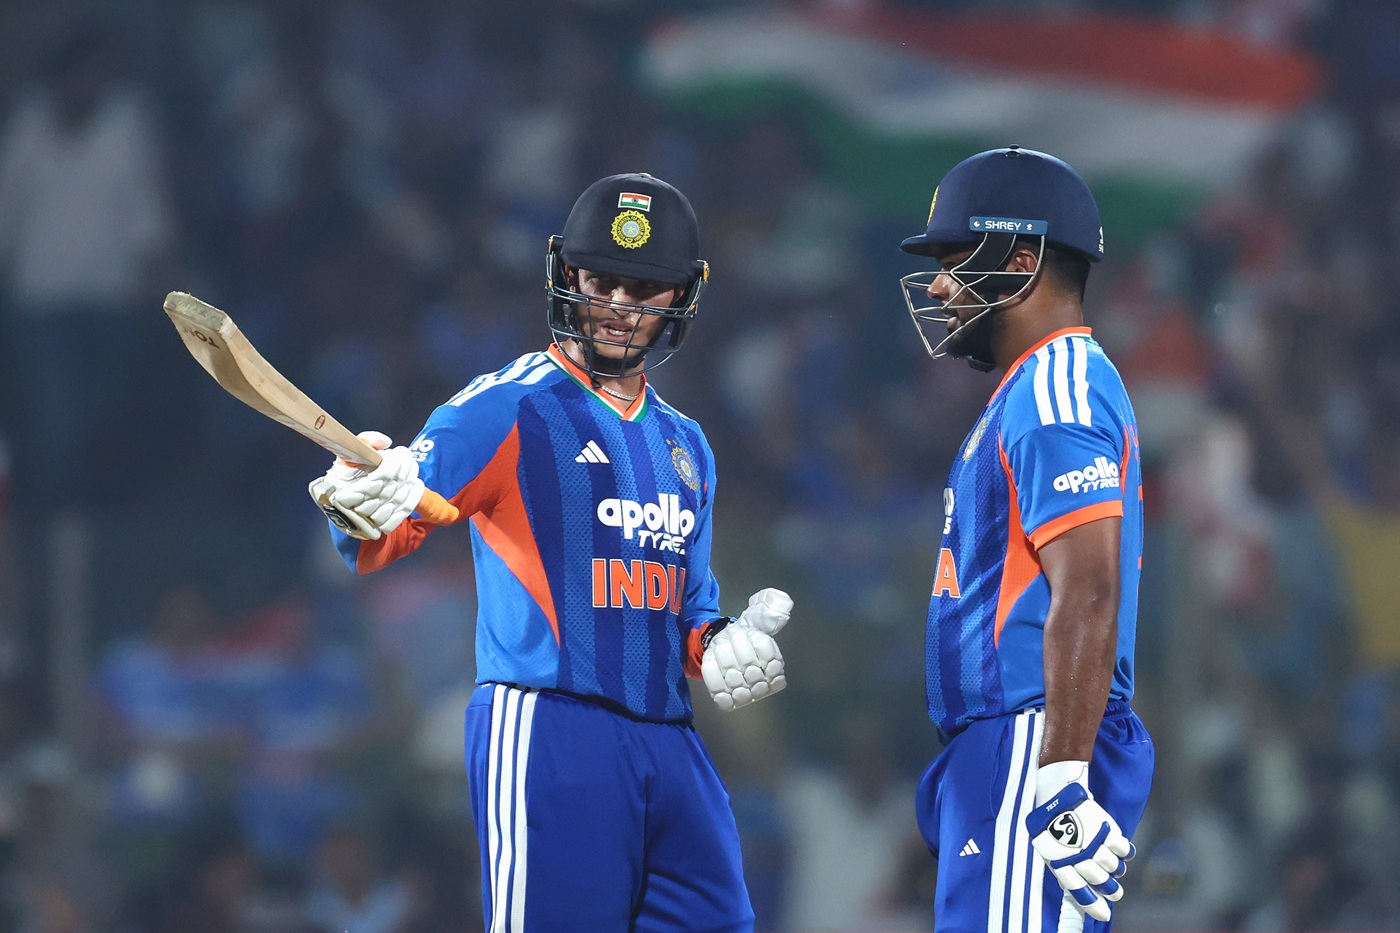
Abhishek Sharma sets Indian record with 30-ball T20I century against England
Abhishek Sharma smashed the fastest T20I century by an Indian batter during the third and final T20I at Arun Jaitley Stadium. He reached the milestone off just 30 balls, finishing with a 34-ball knock of 108 runs. His innings included 11 sixes and nine fours in a dominant display of aggressive batting. The feat saw him break the previous record held by former India captain Rohit Sharma. Abhishek celebrated the historic hundred with a yoga-inspired pose on the field.
0
0
ProgrammingDEV Community ·
Six Data Errors Later, a Digital Twin Yields Fiskardo's Real Evacuation Time
A geospatial analysis using pgRouting's Dijkstra algorithm was conducted to estimate road evacuation time from Fiskardo, a village on the Greek island of Kefalonia, in a wildfire scenario. The process uncovered six successive errors, including a stale road network table, a mislabeled cost column conflating meters with minutes, mismatched coordinate reference systems, and unsorted query results. A suspected connectivity gap in the coastal road data caused the router to favour a 29 km inland mountain route over a 15 km coastal alternative. After correcting all identifiable errors, the analysis concluded that evacuation to Agia Effimia Marina would take approximately 44 minutes across 116 road segments. The exercise highlights that in safety-critical geospatial work, a result's value lies in how rigorously it has been stress-tested, not merely in whether the query executes successfully.
0
ProgrammingDEV Community ·
Semrush Study: AI Citation Sources Shift Based on Query Type and User Intent
Semrush has released a focused mini study examining how AI platforms select citation sources differently depending on query type and user intent. The research, part of the company's AI Visibility Index initiative and backed by 126 million prompts, compares citation patterns for high-stakes YMYL queries against everyday commercial queries. Four platforms were assessed — ChatGPT, Google AI Mode, Google AI Overview, and Gemini — across 22 topics using US data with a UK cross-check. The study found that government sources, community content, and brand-owned domains each appear at different rates depending on the nature and intent of a query. Semrush concludes that optimising for AI citation visibility requires a context-specific strategy rather than a single universal content approach.
0
ProgrammingDEV Community ·
How Web3 Economic Activity Builds Businesses Layer by Layer
A new framework for understanding Web3 proposes mapping the ecosystem by economic activity rather than by blockchain infrastructure. The model identifies nine layers, starting from destination applications like trading and lending platforms at the top, down to base blockchain settlement infrastructure at the bottom. Successful applications such as Uniswap, Aave, and Polymarket generate demand that spawns businesses across adjacent layers, including data tools, risk management, wallets, and developer infrastructure. Each layer exists because real user activity at higher levels creates problems that need solving, making application adoption the engine of the broader ecosystem. The framework also notes that capital, liquidity, and autonomous software cut across all layers, and that many companies intentionally operate at multiple levels simultaneously.
0
SportsESPNcricinfo ·
Abhishek Sharma hits fastest T20I century by a Full Member nation batter
India opener Abhishek Sharma smashed a century off just 30 balls in a T20 International, setting a new record for the fastest hundred by a batter from a Full Member nation. The feat surpassed the previous India record held by Rohit Sharma, who had reached his century in 35 balls. Abhishek's explosive innings underlined his emergence as a destructive force at the top of India's T20 batting order. The record-breaking knock marks a significant milestone in the young left-hander's international career.